Product Strategy
How to Build an MVP Without Over-Engineering It
Custom auth, role matrices, and microservices can eat the weeks you need to learn if anyone will pay. Here is how to keep an MVP small, safe, and ready to grow.
Picture the architecture diagram for a product with zero paying customers. It has custom authentication with refresh-token rotation, an organization model, a role matrix, a notification service, a billing service, and a plan to split the database when traffic arrives.
Every box is defensible. Together they answer a question nobody has asked yet, which is how this will scale, while the question that decides the business stays open: will a specific person use this and pay for it?
Building an MVP is not permission to ship unsafe software or a rough experience that misleads users. It is a way to make learning cheap. That means keeping the product small enough to change, protecting the people and data involved, and refusing to build operational machinery for a team and a customer base that may never exist. This guide covers how to scope an MVP, what to buy instead of build, how to structure the code, and which corners you must never cut.
The short version:
- Write down the one bet your MVP exists to test, and build only the path that tests it.
- Use managed services for authentication, email, payments, and hosting where they fit.
- Start with one deployable app with clear internal modules, not a set of services.
- Keep real security and backups from day one, and write down what evidence would justify more architecture.
The trap: designing for a company that does not exist
Architecture diagrams make hypothetical requirements feel real. Someone imagines enterprise customers, multiple workspaces, custom permissions, audit exports, and teams releasing independently, and each imagined future adds a box. Slowly the diagram describes the company the founders hope to become, not the product they can test this month.
It happens politely. "We will need teams eventually." "Billing should be its own service." "Let's build our own login so we control the whole experience." None of it is absurd. None of it is evidence either. A forecast is fine for choosing reversible options. It is a poor reason to build something today.
Every system you add has a lifecycle: deployment, monitoring, secrets, access control, alerts, documentation, and someone who knows what to do when it breaks. A service split adds a network boundary and a new way to fail. A custom login makes you responsible for credentials and sessions. A role matrix forces decisions about defaults, invitations, and recovery. Writing the code is only the first invoice.
Small teams feel this hardest. A founder spends a week deciding how nested organizations should work instead of watching one target user try the core task. A second deployment gets built before the first one has a safe rollback. The complexity eats the very time the MVP was meant to save.
Decide what the MVP has to prove
Write the bet in a sentence a customer would recognize: who they are, what hurts, what they do today, and what behavior would show your product is better. "Teams need a workflow automation platform" cannot guide anything. "A small property manager will pay to stop copying maintenance requests from email into a shared spreadsheet" tells you exactly what to build first.
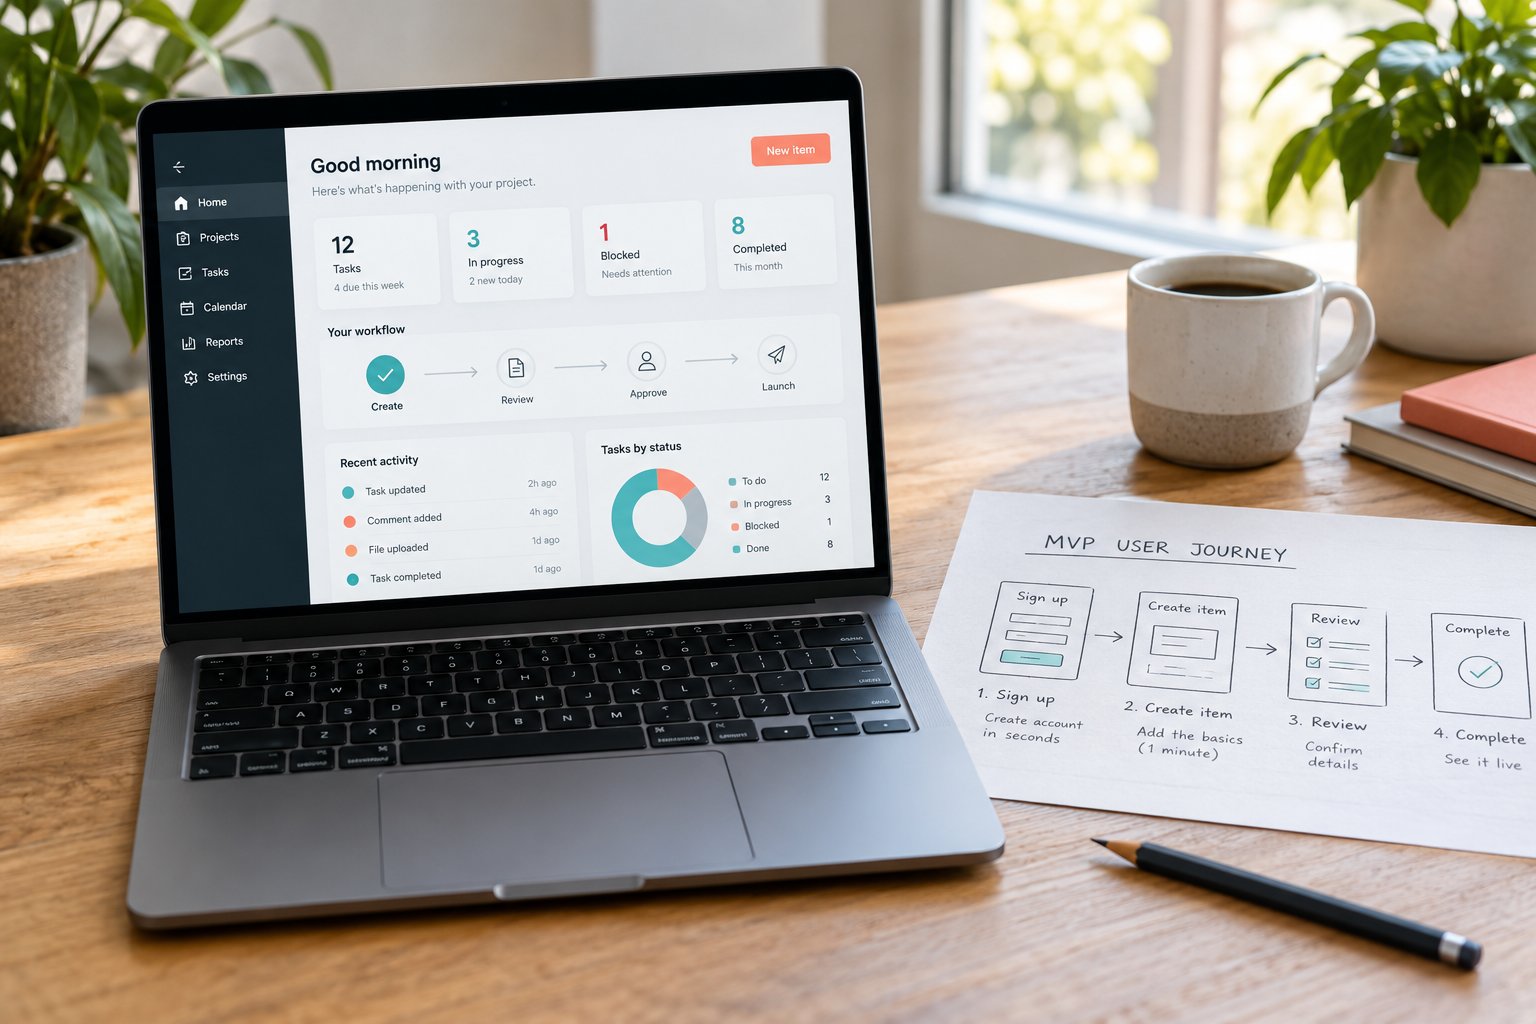
Then draw the shortest path from first contact to evidence. Maybe the user signs in, creates one item, invites one colleague, completes one action, and sees a result. Which of those steps really need to be software? Which can you handle by hand behind the scenes while volume is low?
Make the test falsifiable. "Launch and see what happens" is not a plan. Decide who will try it, how many sessions you can watch, what counts as success, and what would make you change direction. Someone telling you the idea sounds useful is weak evidence. Someone coming back, inviting a coworker, or paying is strong evidence.
Let the biggest risk set the scope. If the unknown is whether the workflow makes sense, build the smallest reliable version of that workflow. If the unknown is whether anyone will pay, show a real price and make a real offer. If regulation or sensitive data is central to the product, investigate that before you collect any.
Buy the boring parts
Authentication looks simple until it becomes a security responsibility. Password reset, email verification, session renewal, suspicious login detection, multi-factor authentication, account recovery, and session invalidation each hide edge cases. A managed identity provider takes most of that burden off you. It does not remove the need to pick a trustworthy provider, configure it carefully, or protect the rest of your system.
Start with the simplest sign-in method that suits your users and your risk. Keep authorization close to the data it protects. A logged-in user is not allowed to read every record, so tenant and ownership checks still have to run on the server for every relevant operation.
The same logic applies to email delivery, file storage, payment processing, monitoring, and often the database. None of them is your product's edge. Your value is in how they are combined to solve a customer's problem. Keep a proportionate exit plan: know how to export your data, rotate credentials, and replace a provider if a constraint changes.
"Managed" is not automatically better. Compare cost, data residency, usage limits, failure behavior, support, portability, and contract terms. The right MVP choice minimizes total learning and operating cost under the requirements you actually have, not under the ones you imagine.
Give the operational basics the same attention. Use a repeatable deployment, keep secrets out of source control, capture enough logs to debug a failed core flow, take backups, and practice restoring them. These are not enterprise decorations. They stop a cheap experiment from turning expensive because one laptop held the only copy of the product.
Start with a modular monolith
One deployable application can still have clear boundaries. Keep product areas in separate modules, define the interfaces between them, and make it obvious which module owns each rule and each piece of data. That is very different from dumping unrelated code into one folder. It is one app that is easy to run and change, with enough internal structure to evolve as evidence comes in.
Keep the layers few: an interface, an application layer for the core use cases, domain rules that express the product's behavior, and adapters for storage and outside services. The folder names matter less than keeping dependencies easy to follow. Do not pass database details through every screen. Do not build a generic framework whose only job is to hide the framework you already use. Add an abstraction when a real change in requirements or testing calls for one.
A modular core keeps your options open. If sending email becomes a real reliability problem, there is already a place to add a queue and a worker. If one capability needs independent deployment, a defined interface gives you a starting point for extracting it. You do not have to deploy those pieces on day one to make a later split possible, and a boundary inside one process is far cheaper to maintain than one across a network.
Extract a service only for a cost you can measure: one area needs to scale on its own, releases keep blocking each other, a team needs to own a capability end to end, or a reliability boundary justifies the operational overhead. AWS's guidance frames the monolith versus microservices choice as a trade-off between scale, complexity, latency, and operational burden. See its workload segmentation guidance. Split for a reason you can observe, not because a conference slide had more boxes.
The security floor you cannot skip
Some shortcuts are not reversible product decisions. Do not expose private records because server-side authorization takes time. Do not store raw passwords or payment details because the MVP is "temporary". Do not put a secret in client code, accept arbitrary uploads without controls, or collect personal data without a clear purpose. Your first users deserve a real security boundary even if the product has one workflow.
At a minimum, know what information the product handles, who should access it, where it is stored, how it is backed up, and how an account or its data can be deleted. Enforce access rules on the server, validate input at every trust boundary, use secure transport, keep dependencies updated, and log security-relevant events without turning your logs into a second copy of customer data. If the product touches health, finance, children's data, employment, or regulated operations, get qualified advice before you collect or process any of it.
Authorization is where early prototypes most often go wrong. A user ID sent from the browser is not proof the user owns a record. A hidden button is not access control. For every read and write, verify that the signed-in user may act on that specific resource. If there is only one role today, write that simple rule down and test it instead of building a role matrix for roles nobody has asked for.
Managed identity does not solve session security by itself either. The provider handles authentication machinery, but your app still has to validate tokens, protect sessions, make correct authorization decisions, and handle account lifecycle events. OWASP's authentication cheat sheet is a solid baseline for what stays with your team.
Think of security as a floor, not a feature list. Here is a quick way to sort the work:
- Build now: server-side authorization on every read and write, managed login, backups you have restored once, repeatable deployments, logs for the core flow.
- Wait for evidence: multi-region failover, fine-grained enterprise permissions, a separate billing service, a custom login system, a queue before any workload needs one.
The line is real risk to real users, not whether a feature sounds advanced.
Write down your upgrade triggers
Future-proofing works better when it is specific. Write down what evidence would justify a bigger architecture. For example:
- The current deployment cannot meet a measured availability target.
- One module uses a disproportionate share of compute.
- Two teams keep blocking each other's releases.
- A customer needs a permission model your one-role rule cannot express.
- A compliance requirement calls for a separate trust boundary.
Attach a review date to each trigger, and do not pay for the full solution until one fires. Keep the data model easy to understand, use stable identifiers, document your outside dependencies, and keep backups portable. Those habits preserve your options without building the imaginary future on speculation.
A few things deserve earlier investment because they are expensive or unsafe to change later: data ownership, tenant boundaries, payment records, audit obligations, and the identity lifecycle. Separate those foundations from speculative scale machinery by asking what must be true for the product to work responsibly today, and what evidence would make tomorrow's cost worth paying.
Keep the trigger list short. If every decision has a trigger attached, you are writing an infrastructure roadmap instead of building a product. Review it like a feature backlog and promote a trigger only when a customer, an operating measure, or a legal requirement backs it up.
A realistic first week
A useful first release plan is concrete and deliberately small:
- Day 1: write the promise and choose the behavior that would support or reject it.
- Day 2: sketch the core journey with real users and name the trust and data risks.
- Days 3 and 4: build one end-to-end path using managed services where they fit, and instrument only the events you need to learn from.
- Day 5: test errors and recovery, not a settings page nobody asked for, then put it in front of real people.
When someone tries the product, watch without coaching them. Note where they hesitate, what they expect to happen, what information they trust you with, and whether the result is useful enough to come back for. Interview them afterward, but separate compliments from actions. If they do not finish the core workflow, find out why before you add another service or permission role.
Once evidence arrives, change the product on purpose. A repeated misunderstanding may call for clearer language or a simpler flow. A missing team feature may justify an invitation path. A real payment commitment may justify dependable billing operations. A concrete workload may justify a queue. Each investment should trace back to a behavior or an operating constraint you have now observed.
The small system is not the final system. It is the shortest responsible path to better information. Build enough structure that the next change is possible, enough security that the experiment does not put users at risk, and no more architecture than the product has earned. The weeks you save are not a prize for writing less code. They are time handed back to the work that decides whether there should be a bigger company at all.
Planning an MVP and unsure what to build first? Email [email protected] and we will help you scope it.
Checkout Engineering
Safari Autofill Breaking Your Checkout? Find and Fix It
A filled-in checkout form can still refuse to submit in Safari. Here is why autofill leaves validation stale, and how to debug, fix, and test it.
7 min read
Read article
Web Performance
Slow Checkout Page? Audit the Third-Party Scripts First
Analytics, chat, reviews, and A/B tests all compete with your payment form. Here is how to audit checkout scripts without losing the data you need.
7 min read
Read article